AI Tools · Researched comparison

7 Best AI Evaluation Tools for Production Options for 2026

TaskReports may earn a fee from some links on this page, and some placements are paid and labelled. Neither one decides the order. See our disclosure.

The short answer

For pytest-style automatic AI testing, DeepEval is where this list starts. Alternatives: Braintrust for production evaluation with collaboration, and Langfuse for open-source tracing and evaluation. All 7 tools are compared below on price, free plan and limits.

On this page

Key takeaways

  • Top of the list is DeepEval, which targets pytest-style automatic AI testing.
  • Free access is easy to find: 7 of the 7 tools have a free plan, for example DeepEval, Braintrust, Langfuse and LangSmith.
  • Confident AI has the lowest monthly starting price in this list: $9.99 per user per month.
  • Promptfoo suits prompt and model comparison in CI.

Quick comparison

ToolBest fitStarts atFree option
------------
DeepEvalPytest-style automatic AI testingFreeYes
BraintrustProduction evaluation with collaboration$249 per monthYes
LangfuseOpen-source tracing and evaluationSee websiteYes
LangSmithLangChain teams needing tracing and review$39 per seat per monthYes
Confident AIHosted system for DeepEval users$9.99 per user per monthYes
TruLensExplainable RAG evaluation for researchersFreeYes
PromptfooPrompt and model comparison in CIFreeYes
★ Best overall

DeepEval

Pytest-style automatic AI testing

  • CI integration
  • More than a dozen built-in metrics

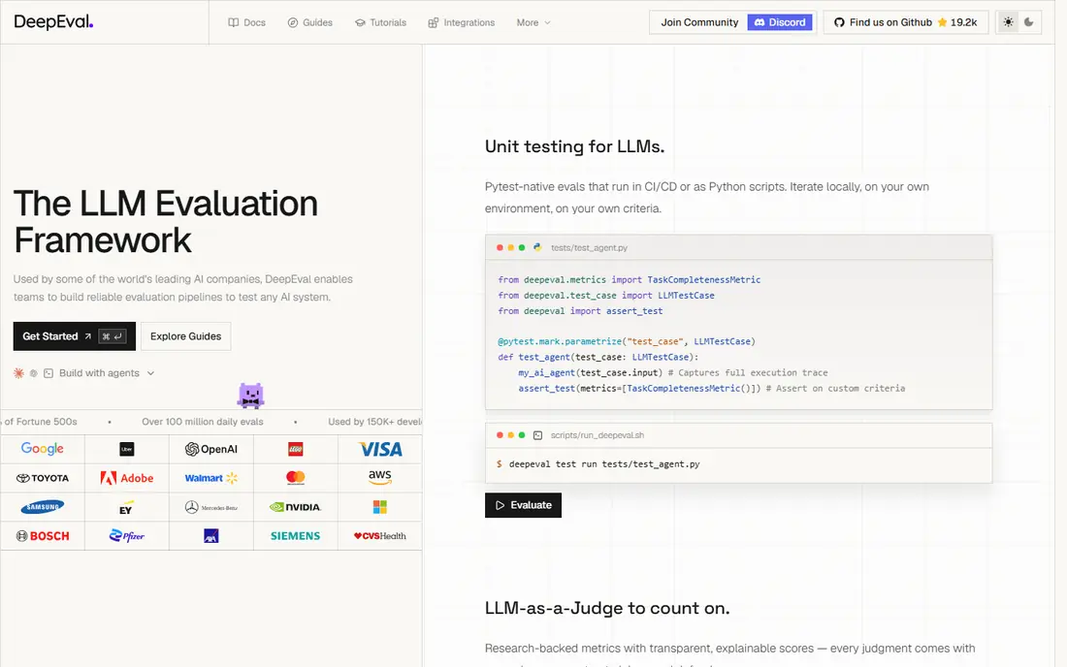
DeepEval makes the most sense for pytest-style automatic AI testing. DeepEval stands out for pytest-style automatic AI testing, and it is simple to see why. In daily use, the workflow stays short for repeat jobs, and most settings are simple to find without a manual. Entry price for DeepEval: Free. You can start on DeepEval without paying. Limits to weigh: Judge costs still apply.

Price: Free

Free plan: Yes

Website: deepeval.com

Watch out for

  • Hosted system is a separate premium product
2

Braintrust

Production evaluation with collaboration
$249 per month

Pick Braintrust if this describes you: production evaluation with collaboration. Among tools for production evaluation with collaboration, Braintrust keeps the workflow short and clear. It merges evaluation datasets, scoring, and production logging in one interface, which helps product and engineering teams review the same cases. Watch-outs: No self-hosting for most teams. For everyday use, in daily use, the workflow stays short for repeat jobs, and most settings are simple to find without a manual. On the other side, premium entry is higher than open-source choices; no self-hosting for most teams. That balance of strength and limits is what should drive your choice, not the headline feature list. Entry price for Braintrust: $249 per month. Braintrust has a free plan.

Free plan: Yes

Website: braintrust.dev

Strengths

  • Dataset versioning
  • Refined review interface

Watch out for

  • Premium entry is higher than open-source choices
3

Langfuse

Open-source tracing and evaluation
See website

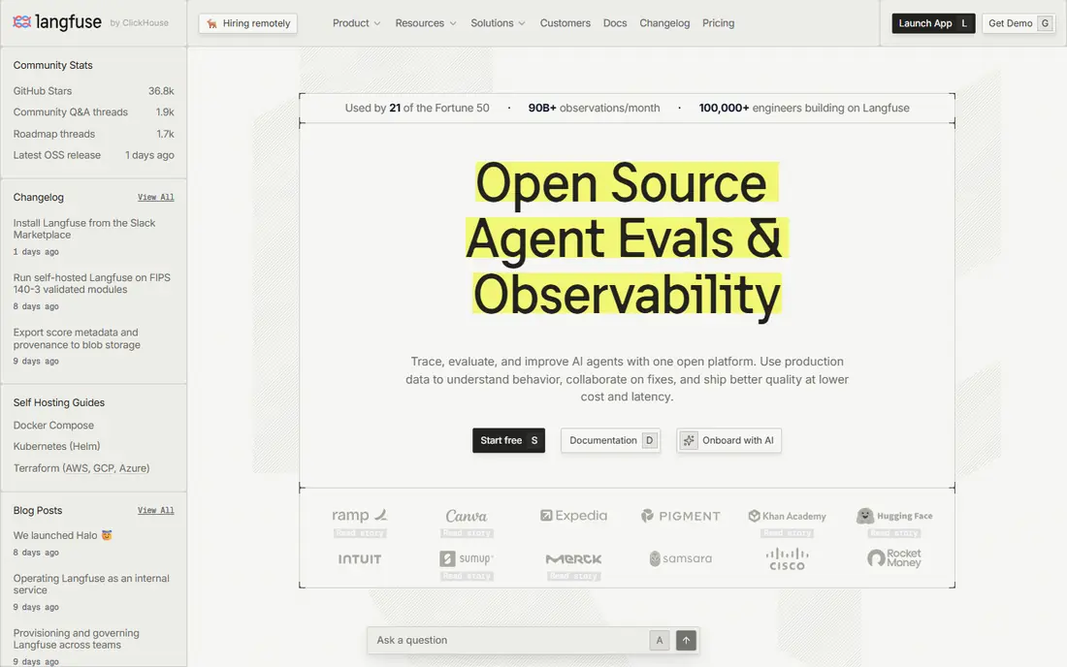
Choose Langfuse for open-source tracing and evaluation. It records traces and lets teams attach scores to them, so production samples can feed back into evaluation datasets. Its primary strengths are open-source core; self-hosting choice; tracing plus custom scores. Downsides: premium plan details vary by source. In practice, on the other side, premium plan details vary by source; setup takes engineering time. That balance of strength and limits is what should drive your choice, not the headline feature list. From a buyer's view, in daily use, the workflow stays short for repeat jobs, and most settings are simple to find without a manual. Langfuse shows no starting price here, so confirm the cost on the vendor site. Langfuse offers a free plan.

Free plan: Yes

Website: langfuse.com

Strengths

  • Self-hosting option
  • Tracing plus custom scores

Watch out for

  • Setup takes engineering time
4

LangSmith

LangChain teams needing tracing and review
$39 per seat per month

LangSmith is designed for LangChain teams needing tracing and review. It ties traces, datasets, and human feedback together, which makes it simpler to find why a model answer changed after a prompt edit. Its primary strengths are deep langchain integration; annotation queues; tracing and production monitoring. Watch-outs: Best value inside LangChain. the main limit is worth weighing before you commit, notably if you work with sensitive files every day. From a buyer's view, in daily use, the workflow stays short for repeat jobs. Most settings are simple to find without a manual. On cost, LangSmith starts like this: $39 per seat per month. LangSmith has a free plan.

Free plan: Yes

Website: langchain.com/langsmith

Strengths

  • Deep LangChain integration
  • Tracing and production monitoring

Watch out for

  • Free level is small for active teams
5

Confident AI

Hosted system for DeepEval users
$9.99 per user a month

Pick Confident AI if this describes you: hosted product for DeepEval users. Its central strengths are hosted deepeval runs; team collaboration; tracing allowance on entry plans. More specifically, on the other side, entry plan limits tracing volume; judge token costs are separate. Trade-offs to know: Judge token costs are separate. On top of that, if that trade-off suits your daily work, it is a solid pick. If not, another tool below may fit better. Entry price for Confident AI: $9.99 per user per month. Free access exists with Confident AI.

Free plan: Yes

Website: confident-ai.com

Strengths

  • Hosted DeepEval runs
  • Team collaboration

Watch out for

  • Entry plan limits tracing volume
6

TruLens

Explainable RAG evaluation for researchers
Free

TruLens targets explainable RAG evaluation for researchers. TruLens stands out for explainable RAG evaluation for researchers, and it is simple to see why. It scores retrieval, grounding, and answer relevance as a linked set, which helps research teams explain why a RAG answer should or should not be trusted. Where it falls short: Smaller community than bigger systems. Its primary strengths are rag triad feedback functions; model versioning; open-source code. The main limit is worth weighing before you commit, notably if you work with sensitive files every day. In daily use, the workflow stays short for repeat jobs, and most settings are simple to find without a manual. Entry price for TruLens: Free. TruLens includes a free tier.

Free plan: Yes

Website: trulens.org

Strengths

  • Model versioning
  • Open-source code

Watch out for

  • Enterprise support is separate
7

Promptfoo

Prompt and model comparison in CI
Free

Promptfoo works best for prompt and model comparison in CI. Promptfoo is built with prompt and model comparison in CI in mind, instead of as an afterthought. It runs prompts against plenty of models and checks outputs with rules or judge models, which makes prompt regressions visible in pull requests. Promptfoo pricing: Free. Promptfoo offers a free plan. Drawbacks to consider: No hosted annotation workflow.

Free plan: Yes

Website: promptfoo.dev

Strengths

  • Multi-model comparison
  • Red-team attack tests

Watch out for

  • Enterprise features are quote-based

FAQ

What is an AI evaluation tool?

It is software that scores language model outputs against metrics, datasets, or human labels. So teams can compare prompts, models, and code changes before and after release.

Which tool is a good match for RAG apps?

DeepEval is the pick this page puts first, mainly for pytest-style automatic AI testing. If your situation differs, Braintrust suits production evaluation with collaboration, and Langfuse suits open-source tracing and evaluation. Compare price and limits before you decide.

Do these tools publish their prices?

Not all of them. Langfuse publishes no starting price, so expect a quote request for it. The rest, DeepEval included, show a starting price, though seats and billing terms still change the final cost.

How are the tools for AI evaluation tools for production ordered?

DeepEval sits first and Promptfoo last because the order follows typical fit for AI evaluation tools for production, then price clarity and free access. It is a judgement call, so read each profile for fit and limits.

Is DeepEval the right pick for everyone comparing AI evaluation tools for production?

No single tool suits every team. DeepEval comes first because it fits pytest-style automated AI testing, while Braintrust suits production evaluation with collaboration and Langfuse suits open-source tracing and evaluation. Match the tool to your own size, budget and workflow before deciding.

Do I need human annotation?

For subjective quality, safety, and brand fit, yes. Automatic judges are quick and consistent, but humans catch nuance that judges miss, notably on edge cases.